Overview
A decade ago the maxim “always be testing” was shorthand for growth. Today it is increasingly a recipe for overspend and instability. In a clear-sighted new piece, Purna Virji argues that the old mantra no longer fits an advertising landscape of tighter budgets, fragmented signal and longer algorithm learning periods. Her prescription is not to test more but to build smarter experimentation systems powered by agentic AI. (searchengineland.com)
The hidden cost of unstructured testing
Unstructured testing used to look like a stack of hypotheses thrown at the wall: multiple audiences, creative swaps and budget shifts launched together in the hope that something stuck. That approach now carries a measurable price. Industry evidence and practitioner reports show ad sets caught in platform learning phases often suffer materially higher cost per acquisition, and every significant change risks resetting optimization and prolonging volatility. (searchengineland.com)
Platforms themselves spell the problem out. Smart bidding systems require time and conversion signal to calibrate — Google, for example, warns the learning period can take up to roughly 50 conversion events or multiple conversion cycles before the bid strategy stabilises. In practice that means a poorly considered test can inflate CPAs for days or weeks. (support.google.com)
From creative factory to experimentation architecture
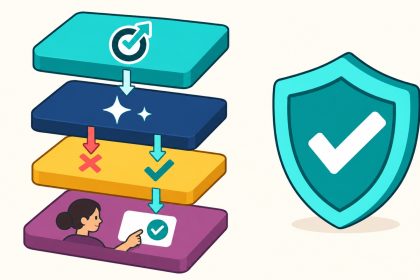
Virji’s central pivot is simple but consequential: stop treating AI as a cheap creative mill and start treating it as an orchestration engine. Rather than asking an LLM to spit out another set of headlines, ask an agentic AI to design the next experiment that fits your budget, risk tolerance and the account’s current learning state. That shift – from quantity of tests to quality of experimental design – is where defensible return on ad spend lives. (searchengineland.com)
A seven-step framework for disciplined testing
Below is a practical, journalist-friendly distillation of Virji’s seven-step approach, rewritten for marketers who must protect scarce budgets and show results.
Step 1 – Set hard guardrails (humans first)
Before AI touches experiments, define firm constraints. Examples: fixed percentage of total media budget for tests (for example 10%), acceptable CPA volatility thresholds, platform-specific learning-reset thresholds, early kill indicators like CTR and engagement drops, and explicit brand-risk boundaries. Put these in a single, referenceable file so any AI agent must consult them before proposing a test. (searchengineland.com)
Step 2 – Let AI audit your experiment history
Feed six months of tests into an AI agent and ask it to map variables changed, durations, platform resets and statistical power. An agent will find waste – repeatedly tested variables with no lift – and flag false negatives where low power hid a meaningful effect. This turns dusty spreadsheets into institutional memory. (searchengineland.com)
Step 3 – Insist on structured hypotheses
Replace vague impulses with falsifiable statements. Weak: “try a new headline.” Strong: “If we emphasise faster time-to-value rather than ease of use, we expect a 10 to 15 percent lift in demo requests from mid-market buyers because win-loss interviews highlight speed as the top decision driver.” Structured hypotheses keep tests interpretable and budget-efficient. (searchengineland.com)
Step 4 – Risk-score every proposed test
Have the AI score proposals across budget impact, algorithm disruption, audience overlap, brand sensitivity and learning value. High risk with low insight is an automatic veto. Low risk and high learning value gets fast-tracked. This forces commercial trade-offs into the testing pipeline rather than leaving them to ad-hoc instincts. (searchengineland.com)
Step 5 – Pre-test with synthetic audiences
One of the most underused AI applications is synthetic testing. Recent research from Stanford and Google DeepMind shows interview-trained generative agents can reproduce human survey responses with high fidelity – roughly 85 percent relative accuracy on benchmark surveys – making them useful for early-stage signal-gathering and creative QA. Use synthetic personas to de-risk big bets before you spend real media. AI is not a replacement for live data yet, but it is cheap and fast for filtering ideas. (arxiv.org)
Step 6 – Sequence tests, do not stack them
AI should act like air traffic control: scan active campaigns, flag conflicts and recommend sequencing so audience, creative and landing-page changes do not all trigger simultaneous learning resets. If overlap is unavoidable, enforce clean holdouts so you retain a reliable source of truth. Sequenced tests deliver clearer signal for less budget. (searchengineland.com)
Step 7 – Build a living knowledge base
Invest in an auto-summarising test repository. For every completed experiment have AI record why a variant won, who it worked with, how durable the lift was and what interactions mattered. Over time this becomes a competitive moat: most teams can replicate targeting; far fewer have a hundred validated customer truths at their fingertips. (searchengineland.com)
What this means for Irish marketers and CFOs
In Ireland, marketing budgets have to survive quarterly scrutiny. The argument for disciplined experimentation is inherently fiscal: you reduce waste, lower the chance of destabilising core campaigns, and create repeatable learning that scales. Begin with three immediate steps: codify experimentation guardrails, run an AI audit on the last six months of tests, and mandate risk scores on any proposal that touches live spend. Use platform guidance on learning periods to set realistic expectations for duration and conversion thresholds. (support.google.com)
A final note on governance
Adopting agentic AI for experimentation requires governance. Make the guardrails auditable, log every agent recommendation, and keep humans accountable for final go-no-go decisions. That combination of algorithmic assistance and human oversight is the best way to compound intelligence without compounding risk.
From activity to architecture
The growth-era instinct to run more tests simply because you can is a luxury fewer organisations can afford in 2026. The smarter play is to build an experimentation engine that privileges risk management, statistical power and institutional learning. As Virji puts it, the goal is not to run more experiments but to compound intelligence. When stakeholders ask why you are not testing every wild idea, show them the architecture and explain that you are not just running experiments – you are building an intelligence engine that protects budget and delivers durable insights. (searchengineland.com)
Further reading and sources
Purna Virji, ‘Always be testing worked in 2016 — it is risky in 2026’, Search Engine Land. (searchengineland.com)
Generative Agents for Market Research – arXiv paper from Stanford and Google DeepMind. (arxiv.org)
Google Ads Help – Duration of the learning period for campaigns and what affects it. (support.google.com)
Related Posts
- Unlock Exclusive Insights with a Subscription
- New Employment Rights Act: Major Milestone for Women’s Workplace Equality
- Get Tonight’s Winning Lotto Numbers: Complete National Lottery Results and Thunderball for Saturday, March 7, 2026!
- Integrated Analytics Reveals Marketing Impact: How to Prove ROI and Boost Campaign Performance
- Top 3 Lithium ETFs Surpass Gold and Silver Returns: Invest Smart Today!